Backpropagation Basic Examples
Disclaimer: This Jupyter Notebook contains content generated with the assistance of AI. While every effort has been made to review and validate the outputs, users should independently verify critical information before relying on it. The SELENE notebook repository is constantly evolving. We recommend downloading or pulling the latest version of this notebook from Github.
Backpropagation
Backpropagation, short for "backward propagation of errors," is a foundational algorithm in the field of machine learning and artificial intelligence. At its core, it is a method used to train artificial neural networks by efficiently computing gradients that guide the optimization of the network's parameters. Introduced in the 1980s, backpropagation became a breakthrough that catalyzed the rapid growth of neural networks and deep learning, which are now central to modern AI applications like natural language processing, image recognition, and recommendation systems.
The importance of backpropagation lies in its ability to adjust the weights and biases of a neural network to minimize errors in predictions. It works by propagating the error, computed at the output layer, backward through the network to update each layer's parameters. This process leverages the chain rule of calculus to compute how changes in the parameters of the network influence the output. By iteratively applying backpropagation during training, the network learns to approximate complex, non-linear relationships within the data.
Learning about backpropagation is crucial because it forms the backbone of how neural networks learn and generalize. Understanding this algorithm allows practitioners to appreciate the inner workings of models they use, diagnose issues such as vanishing or exploding gradients, and make informed decisions about architecture design or hyperparameter tuning. Moreover, concepts derived from backpropagation underpin other advanced techniques, such as transfer learning and fine-tuning pre-trained models.
From a broader perspective, backpropagation exemplifies the synergy between mathematics and computer science in solving real-world problems. It highlights how mathematical principles can be translated into computational algorithms with transformative societal impacts. For anyone entering the field of AI or deep learning, grasping backpropagation is a foundational step toward mastering the broader landscape of machine learning techniques.
---
Preliminaries
Basic Notations
y denotes the output of a function that takes one or more parameters as input, and applies various operations (e.g., addition, multiplication, squaring, logarithm, etc.) to calculate an output.
, , ,... denote input parameters of a multivariable function
, , , ... denote intermediate results based on a subset of operations in
Quick Recap: Chain Rule
Many parametric machine learning models — most prominently neural networks — are trained through minimizing a loss function using gradient-based methods. Here, the model and its performance is determined by the current set of parameters (or weights) . The loss function quantifies this performance, and minimizing the loss function means finding the weights where the model performs best. Gradient-based methods calculate the gradient of the loss function with respect to all weights to then systematically change the weights to decrease the loss.
Calculating the gradient requires calculating the derivative of a function — or all partial derivatives of a multivariable function. In case more complex models such a neural networks, calculating the derivative and therefore the gradient can be quite challenging. The chain rule is essential in calculus because it allows us to differentiate complex functions by breaking them into simpler components. It is widely used in various fields, including physics, engineering, and economics. In machine learning, the chain rule is the mathematical foundation of backpropagation, enabling the computation of gradients for training neural networks.
The chain rule in calculus provides a way to compute the derivative of a composite function. Suppose depends on , and in turn depends on , i.e., and . The chain rule states that the derivative of with respect to can be found by multiplying the derivative of with respect to by the derivative of with respect to .
Here:
is the rate of change of with respect to , is the rate of change of with respect to , is the rate of change of with respect to .
To give a very simple example, consider the function . As a composite function, we can define and . To find , we use the chain rule as follows
Calculate :
Calculate :
Calculate by using the chain rule:
Substitute :
The chain rule is crucial for training neural networks because it enables efficient computation of gradients during backpropagation. These gradients indicate how to adjust weights and biases to minimize prediction errors. By applying the chain rule layer by layer, optimization methods like gradient descent can update parameters effectively, making training deep networks feasible. How backpropagation works in detail using examples is the topic of this notebook.
Computational Graphs
A computational graph is a visual representation used in machine learning and deep learning to depict the sequence of operations performed on data as it moves through a computational process, particularly during forward and backward propagation. Each node in the graph represents a variable or operation (e.g., addition, multiplication, or activation functions), and the edges represent the flow of data between these nodes. The computational graph is a common visualization tool because it provides a clear and intuitive understanding of complex computations. It highlights the dependencies between variables and operations, making debugging and optimization easier. Moreover, modern frameworks like TensorFlow and PyTorch utilize computational graphs internally to manage and optimize the execution of machine learning models, reinforcing their importance as a fundamental concept in deep learning workflows.
To give an example, the figure below shows the computational graph for the function from above. The first node in the graph represents the squaring operation ; the second node represents the calculation .
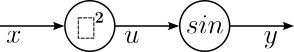
This representation of a composite function using a computation graph is very useful for understanding the underlying concepts of backpropagation.
---
Backpropagation Explained by Examples
Simple Example
Let's start with a very simple example and consider the following multivariable function:
We can define the addition and multiplication operations as their own functions: and . Considering these two operations as nodes, the corresponding computational graph looks as follows:
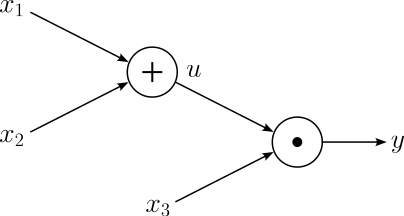
Given this graph, we can already write down the equations for calculating the local gradients for all computational nodes:
Node Local Gradients
Forward Pass
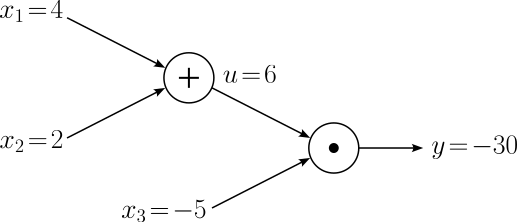
The forward pass is the process of evaluating the mathematical expression represented by computational graphs. Doing the forward pass means passing the values from all inputs in the "forward" direction from the left (input) to the right where the output is. For our example here, let's assume the input values , , and . With that, we can easily calculate the values of and and visualize all values in our computational graph:
Backward Pass
In the backward pass, the goal is now to compute the gradients for each input with respect to the final output . When training neural networks, the inputs of nodes in the computational graphs will include all trainable weights , so we need their gradients to update the weights when using methods such as Gradient Descent. For our example, we need to calculate the following gradients:
The fundamental idea of backpropagation is to calculate all derivatives from the output to the input following the respective path in the computational graph. for example, backpropagation calculates the gradient of by calculating the following partial derivatives using the chain rule:
The first partial derivative , i.e., the partial derivative of the output with respect to the output, seems a bit pointless, but we will see later how it fits the systematic process and backpropagation. Trivially, the gradient for any output value is . And we can add this information about our first gradient into our computational graph.
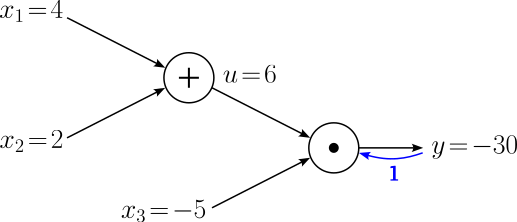
Passing backward through the computational node for the multiplication operation means calculating the gradients with respect to the and . For this, we can apply the chain rule accordingly:
Again, having seems not really required. However, notice that we calculate both gradients by multiplying the gradient coming in from the output of the computational node — which we calculated in the previous step — and the local gradient of the corresponding input node. Furthermore, we also know the local gradients, either because it is an input variable (here ) or an intermediate result we calculated during the forward pass (here ). In other words, while we could calculate again, it is much more efficient to save the result during the forward pass and re-use it for the backward pass. Plugging all values gives us the following gradients:
Let's add these gradients to our computational graph.
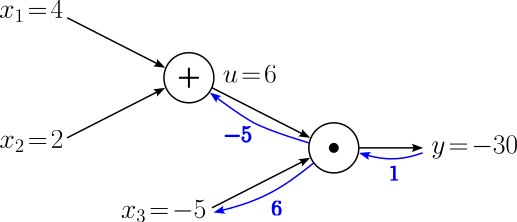
The computational node the backpropagate through is the one for the addition operation to calculate the gradients of the output with respect to and . The process is exactly the same as we just have seen of the multiplication operation. Using the chain rule, we can write:
The shared factor is again the gradient coming in from the output of the computational node we have just calculated. Similarly, the factors are the local gradients of the inputs of the node. We can therefore calculate the last two remaining gradients with respect to the inputs and :
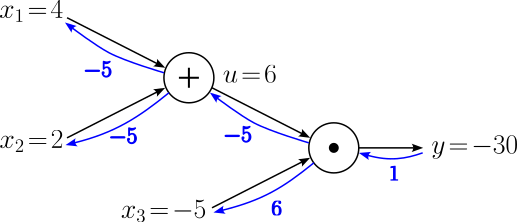
We have now calculated all gradients , , and using backpropagation. Despite this very simple example, we saw the core aspects of backpropagation: (a) the application of the chain rule, and (b) the re-use of the intermediate results calculated during the forward pass.
Advanced Example
For some additional practice, let's extend our initial multivariable function by additional inputs as well as operations. While this does not require any additional step we have not seen before, a more complex function better highlights the benefits of systematically calculating all gradients step by step. In this more advance example, we will work with the following function:
The first step is, again, to split this composite function into meaningful operation. Given that the function is still rather simple, we treat each addition, multiplication, and squaring operation as their own node in the computational graph. This gives us the computational graph as shown below.
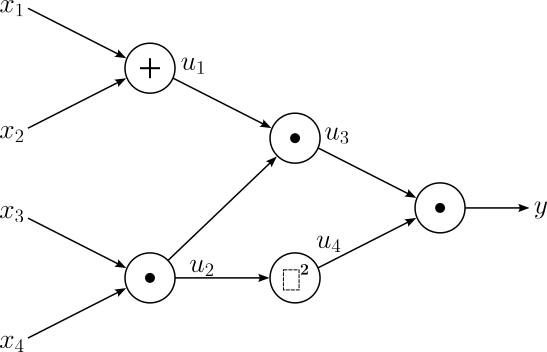
As we need this information later for the backward pass of the backpropagation procedure, let's list all local gradients for each computational node.
Node Local Gradients
Forward Pass
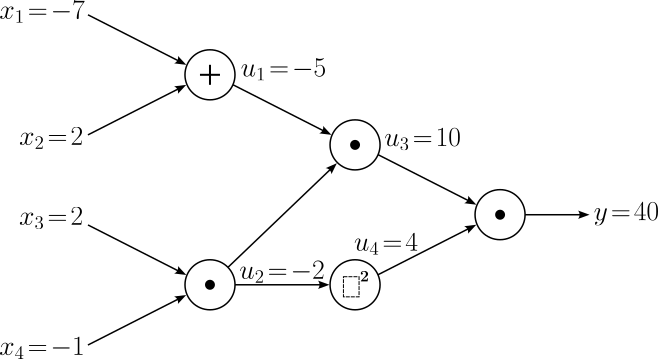
The forward pass is straightforward as usually as we simply calculate the final output as well as all intermediate results as given by the computational graph. We assume that the values for our five input variables are , , , and . The computational below now includes all input values , intermediate results , and the final output value .
Backward Pass
With five inputs, we now need to calculate the gradients of the function with respect to all five input variables. More specifically, we are looking for
Now that the function and therefore the computational graph is a bit more complex, the path from the output to the inputs has also become a bit longer. This means that we have to compute more intermediate gradients. The example below illustrate all the gradients backpropagation will calculate to finally be able to calculate the gradient for :
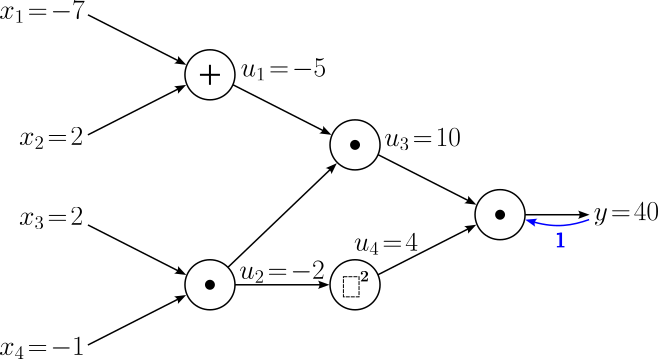
As usual, we begin with our "trivial" gradient . Again, we explicitly include this gradient to adhere to our procedure by calculating all following gradients for each computational node by multiplying the incoming gradient from the output with the corresponding in local gradients. Let's add this "trivial" gradient to our computational graph.
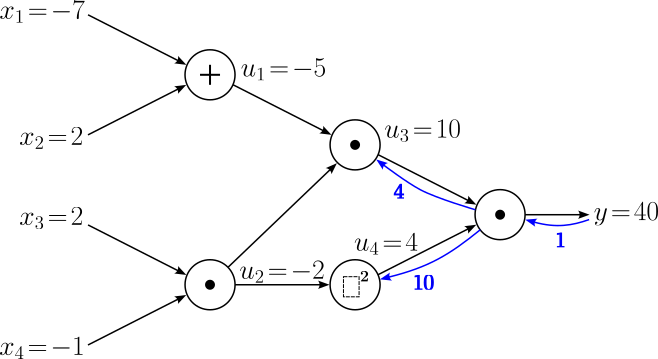
Now the "real" backpropagation starts by considering the first computation node (with respect to the backward pass). Passing backward through the computational node for the multiplication operation means calculating the gradients with respect to the and . For this, we can apply the chain rule accordingly:
Backpropagation ensures that we always have both factors on the right-hand side of the equations. Firstly, we have just calculated on the previous step. And secondly, both gradients and are known since they are they reflect intermediate results calculated during the forward pass, here and . By plugging in those values we get:
Let's add these gradients also to our computational graph.
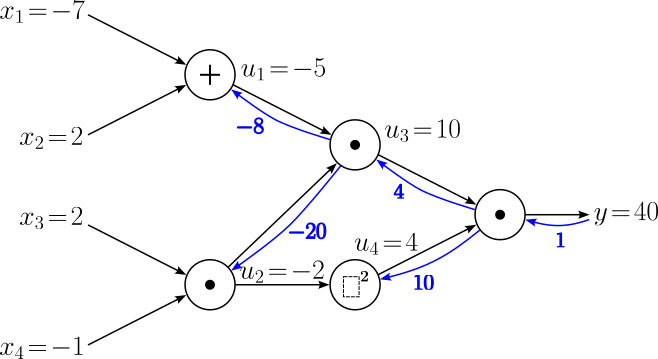
Now the process gets a bit more interesting compared to the simple example as we have two separate operations (i.e., computational nodes) we need to backpropagate through. However, this does not change anything in the process itself, we only have to handle each operation individually to calculate all gradients. So let's start with the multiplication operation that gives us the intermediate result . This means we are interested in the gradients and . However, you might have noticed that node feeds into more than one other node — or simply speaking, the node yielding has two outgoing edges. This means there are two different paths going from that node to the output . When backpropagating through the multiplication node we only cover one path for the time being. Let's annotate this explicitly when applying the chain rule:
We just calculated , and we already know the local gradients and . Together with the intermediate results calculated during the forward pass, we get:
So we have two more gradients we can add to our computational graph.
For the next step, we can consider either the addition operation that resulted in or the squaring operation that resulted in . Let's go with the former, meaning we want to calculated the gradients and , two of the five gradients of the input variables. The chain rules tells us that we can calculate both gradients as:
With and the two local gradients we already know, and evaluate to:
Another two gradients to be added to our computational graph. We are almost there.
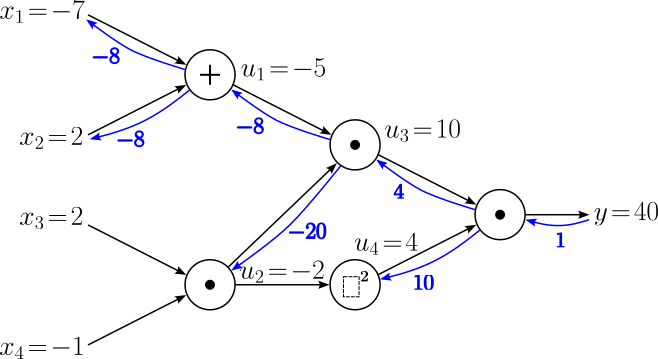
The next computational node we have to backpropagate through is the squaring operations that gave us , which will again(!) give us the gradient for . Notice how we now reached node using the second path. Applying the chain rule — and adding the explicit annotation again — we can calculate this gradient using known information:
Note that here we calculate a single new gradient as the squaring a number is an unary operation. Recall that we have calculated several steps before; see above. And as usual, we also have the value of required local gradient from the forward pass, giving us:
The updated computational graph looks as follows:
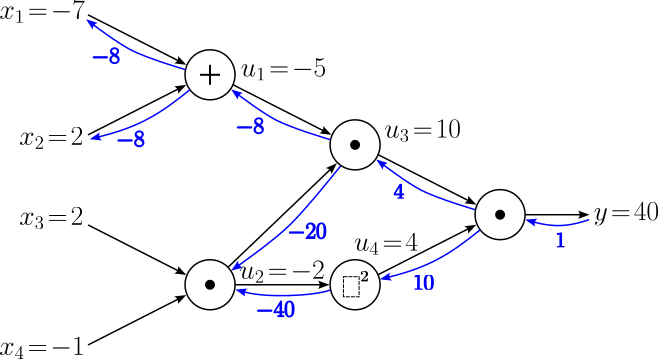
Let's take a short pause and look back on all the calculations so far. Most importantly, we currently have the two gradients and . However, to backpropagate through the last node , we need the gradient . In this situation, we must use an extension of the normal chain rule, called the multivariable chain rule. This rule states that we have to sum up all gradients flowing back into a node. For our example, this mean we have to calculate the as:
For clarity, we can add this result also to our computational graph:
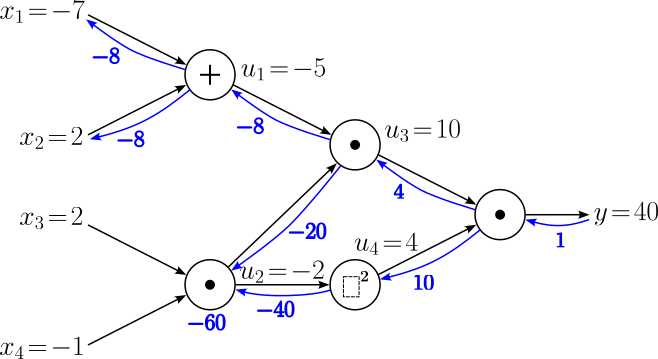
This leaves us with the final computational node to compute the last two gradients with respect to the last two remaining input variables and . So one last time we apply the chain rule
Plugging in all the respective numbers gives us our final gradients.
Now that we backpropagated through all nodes, we have completed the backward pass and have calculated all gradients. Let's have a look at the final computational graph.
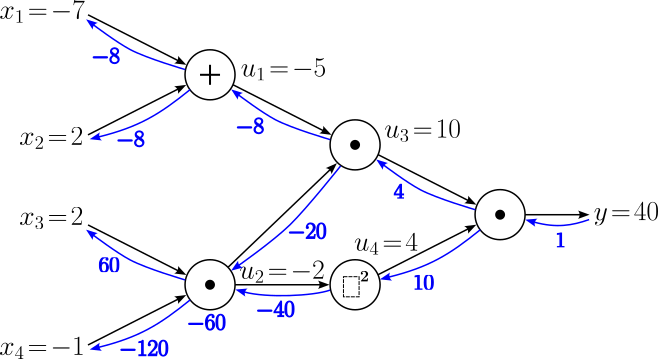
Having gone through this more complex example in full detail, you might find it a bit tedious and boring since we have always performed the same basic steps for each operation (i.e., node in the computational graph). However, this is a good thing since this means that backpropagation is in its core quite simple and systematic, and therefore also rather straightforward to implement. Also appreciate that backpropagation does not only refer to the backward pass. While the backward pass requires some more careful consideration, the forward pass is crucial as it provides us with the intermediate results required to calculate the local gradients needed during the backward pass.
---
Summary
Backpropagation is a foundational algorithm in training artificial neural networks. It efficiently computes the gradients of a loss function with respect to the weights of the network, allowing the model to adjust its parameters to minimize prediction errors. At its core, backpropagation uses the chain rule of calculus to propagate errors backward through the network. The process begins with a forward pass, where inputs are passed through the network to generate predictions. A loss function then quantifies the difference between these predictions and the true labels. During the backward pass, gradients of the loss function are computed layer by layer, starting from the output layer and moving toward the input layer. These gradients indicate how each weight in the network should be adjusted to improve predictions.
The power of backpropagation lies in its ability to handle complex, multi-layer networks efficiently. Combined with optimization algorithms like stochastic gradient descent (SGD), it enables networks to learn from large datasets and improve iteratively. However, the algorithm requires careful initialization of weights and tuning of hyperparameters like the learning rate to avoid issues like vanishing or exploding gradients, which can impede training. Understanding backpropagation is essential for anyone working with deep learning models, as it provides insight into how networks learn and adapt. By grasping its mechanics, practitioners can better diagnose and troubleshoot training issues, optimize model performance, and innovate in neural network design.